Introducing Humanity's Sixth Sense (HSS)
A benchmark measuring the implicit visual reasoning and intuitive understanding we draw from a scene. Built in partnership with Scale AI.
Six examples from HSS. How would you answer?
-
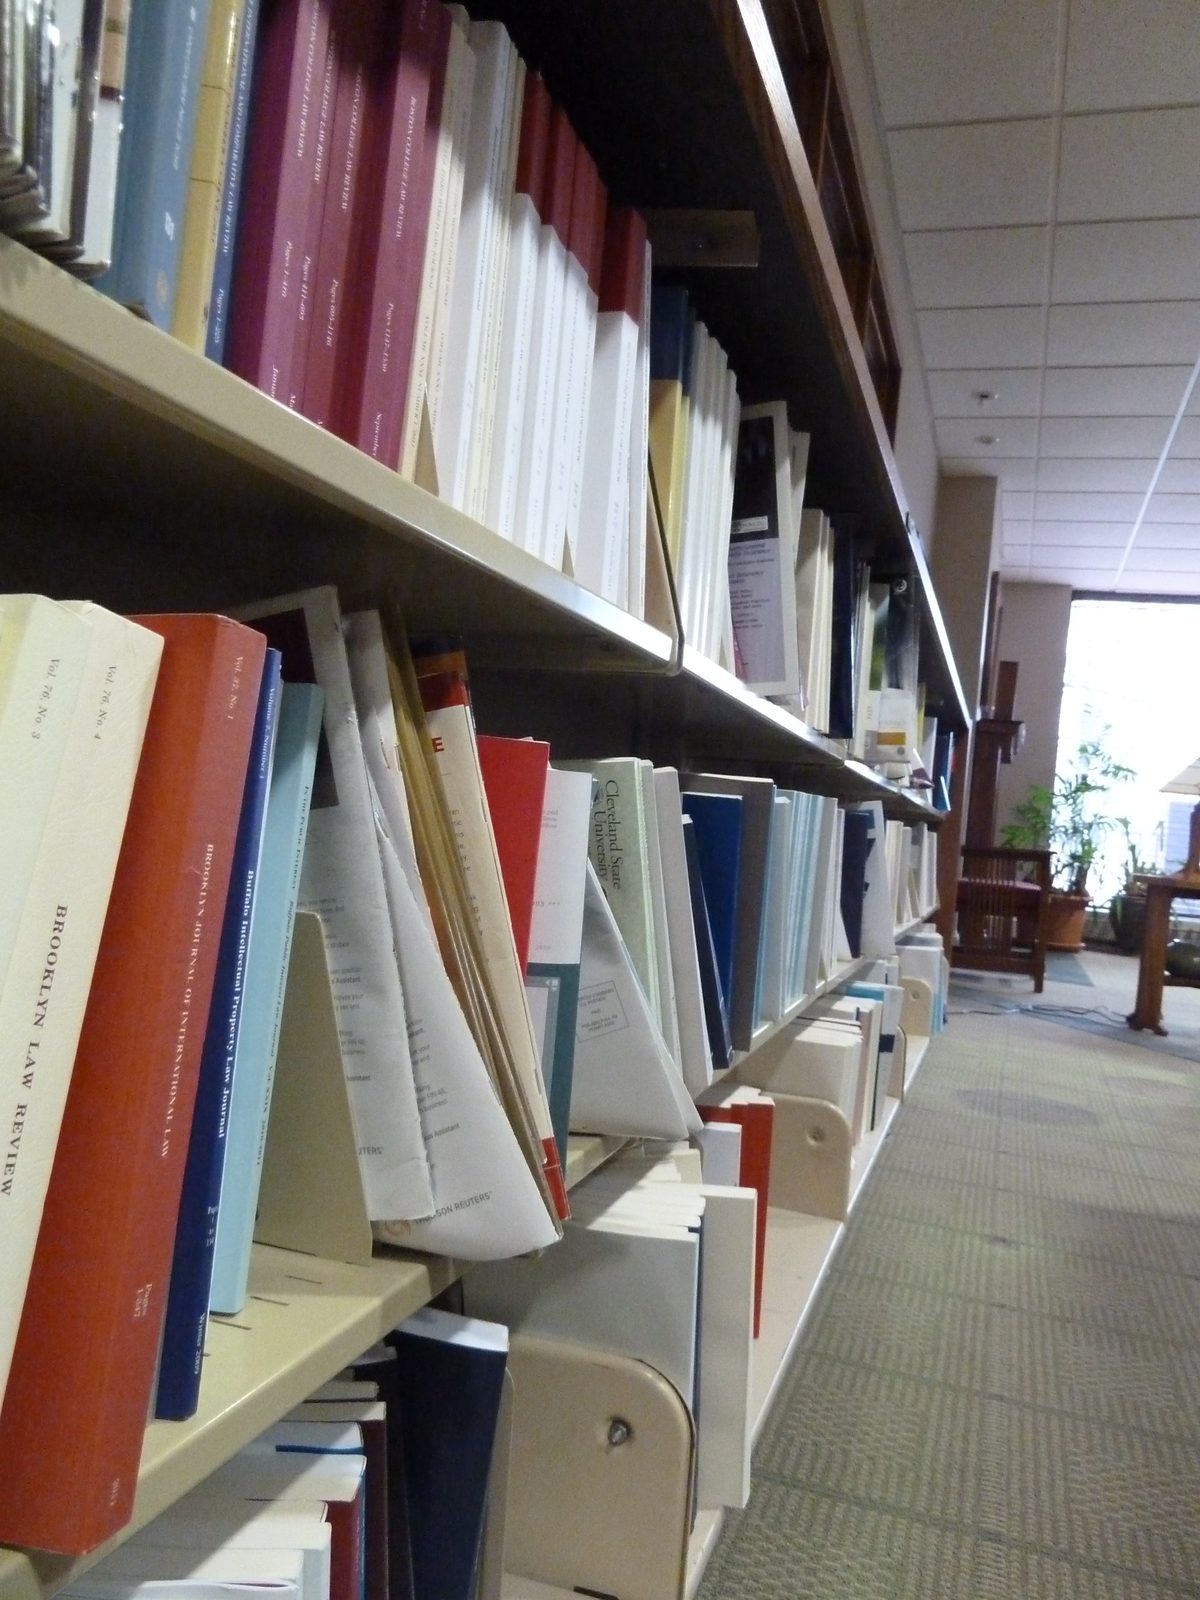
“Law library books” by Janet Lindenmuth, CC BY 2.0. Resized for the web; otherwise unaltered. Would two more white books fit on this shelf?
Yes — in the gaps already there.
In the paper’s evaluation, GPT 6 Astra, Gemini 3.8 Flash and Claude Opus 5.5 each answered “no, there is too little space” on all three attempts. Fig. 10 · affordance & feasibility
-
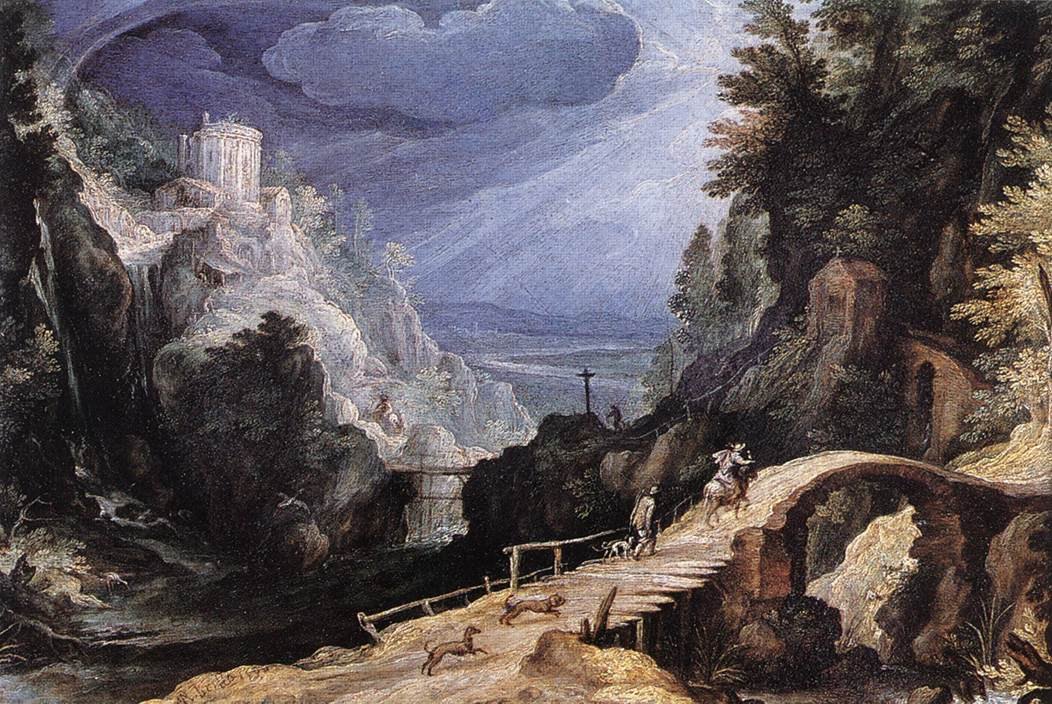
Gebirgslandschaft (Mountain landscape) by Paul Bril (c. 1553–1626). Public domain, via Wikimedia Commons. Resized for the web. From which side of the frame did the traveler with the two dogs enter?
The bottom edge — you can tell by tracing the path back.
In the paper’s evaluation, GPT 6 Astra, Gemini 3.8 Flash and Claude Opus 5.5 each answered “the lower-left side” on all three attempts. Fig. 11 · retrodiction
-
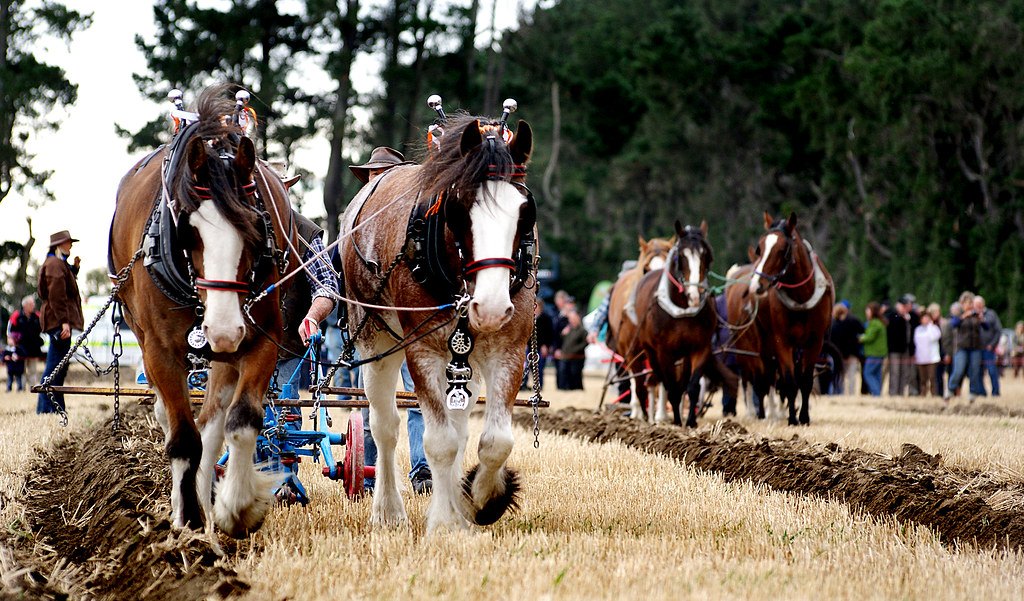
Horse Ploughing (8) by Bernard Spragg, 2010. Public domain, via PICRYL. Are these chains bearing the plough’s drag weight?
Yes — they are taut and loaded.
In the paper’s evaluation, GPT 6 Astra, Gemini 3.8 Flash and Claude Opus 5.5 each answered “no, they hang slack” on all three attempts. Fig. 12 · mechanistic causality
-
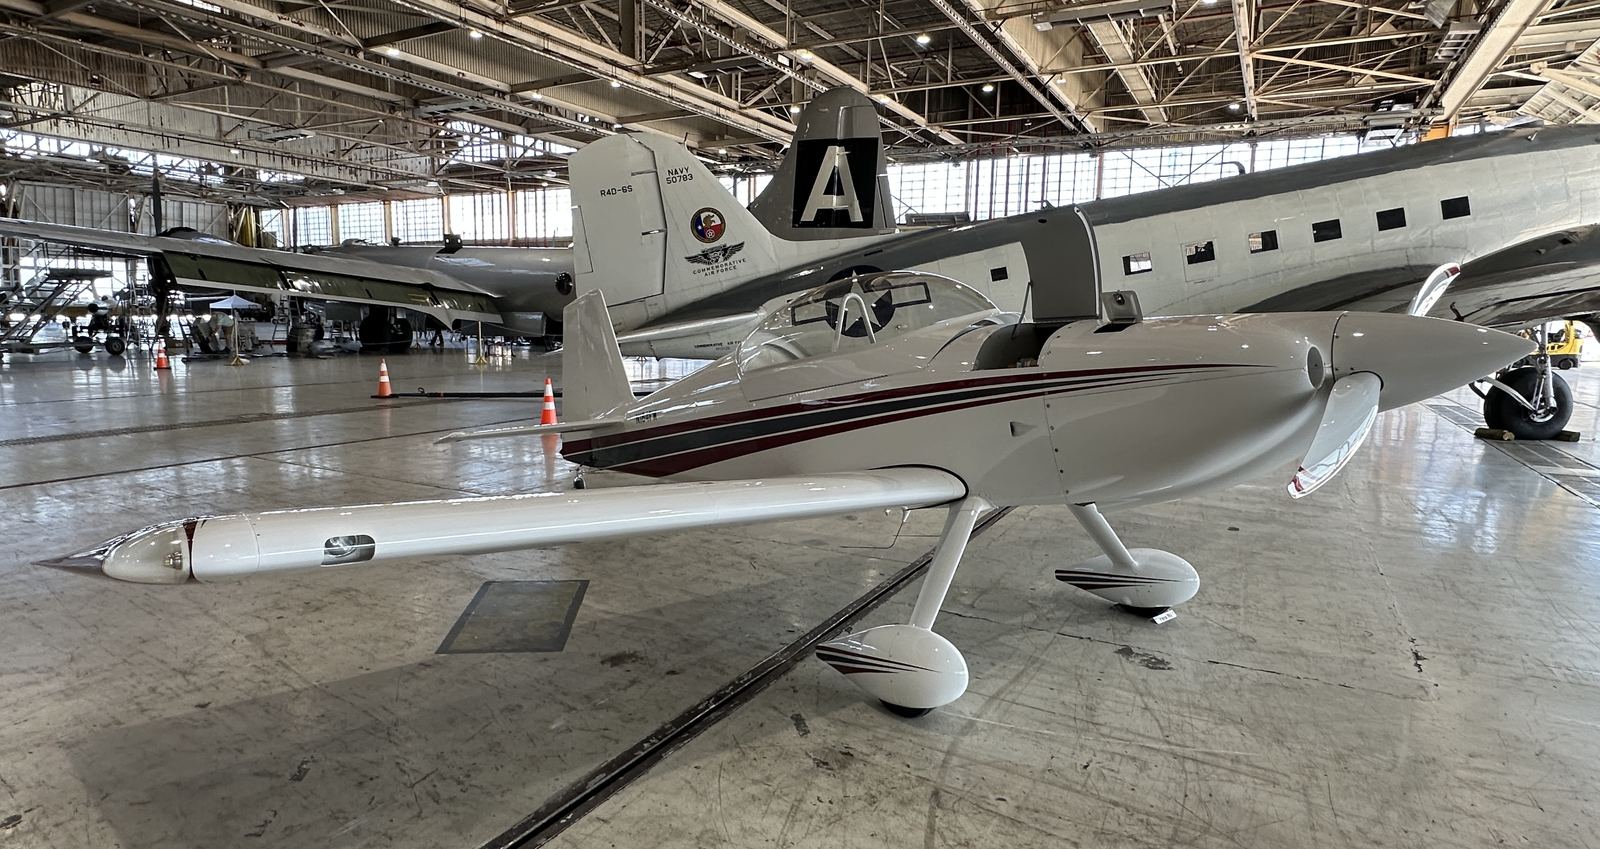
Are the people around the aircraft visitors, or crew preparing it?
Crew — you can tell from the open access panels.
In the paper’s evaluation, GPT 6 Astra, Gemini 3.8 Flash and Claude Opus 5.5 each answered “visitors examining it” on all three attempts. Fig. 13 · social role, norm & power
-
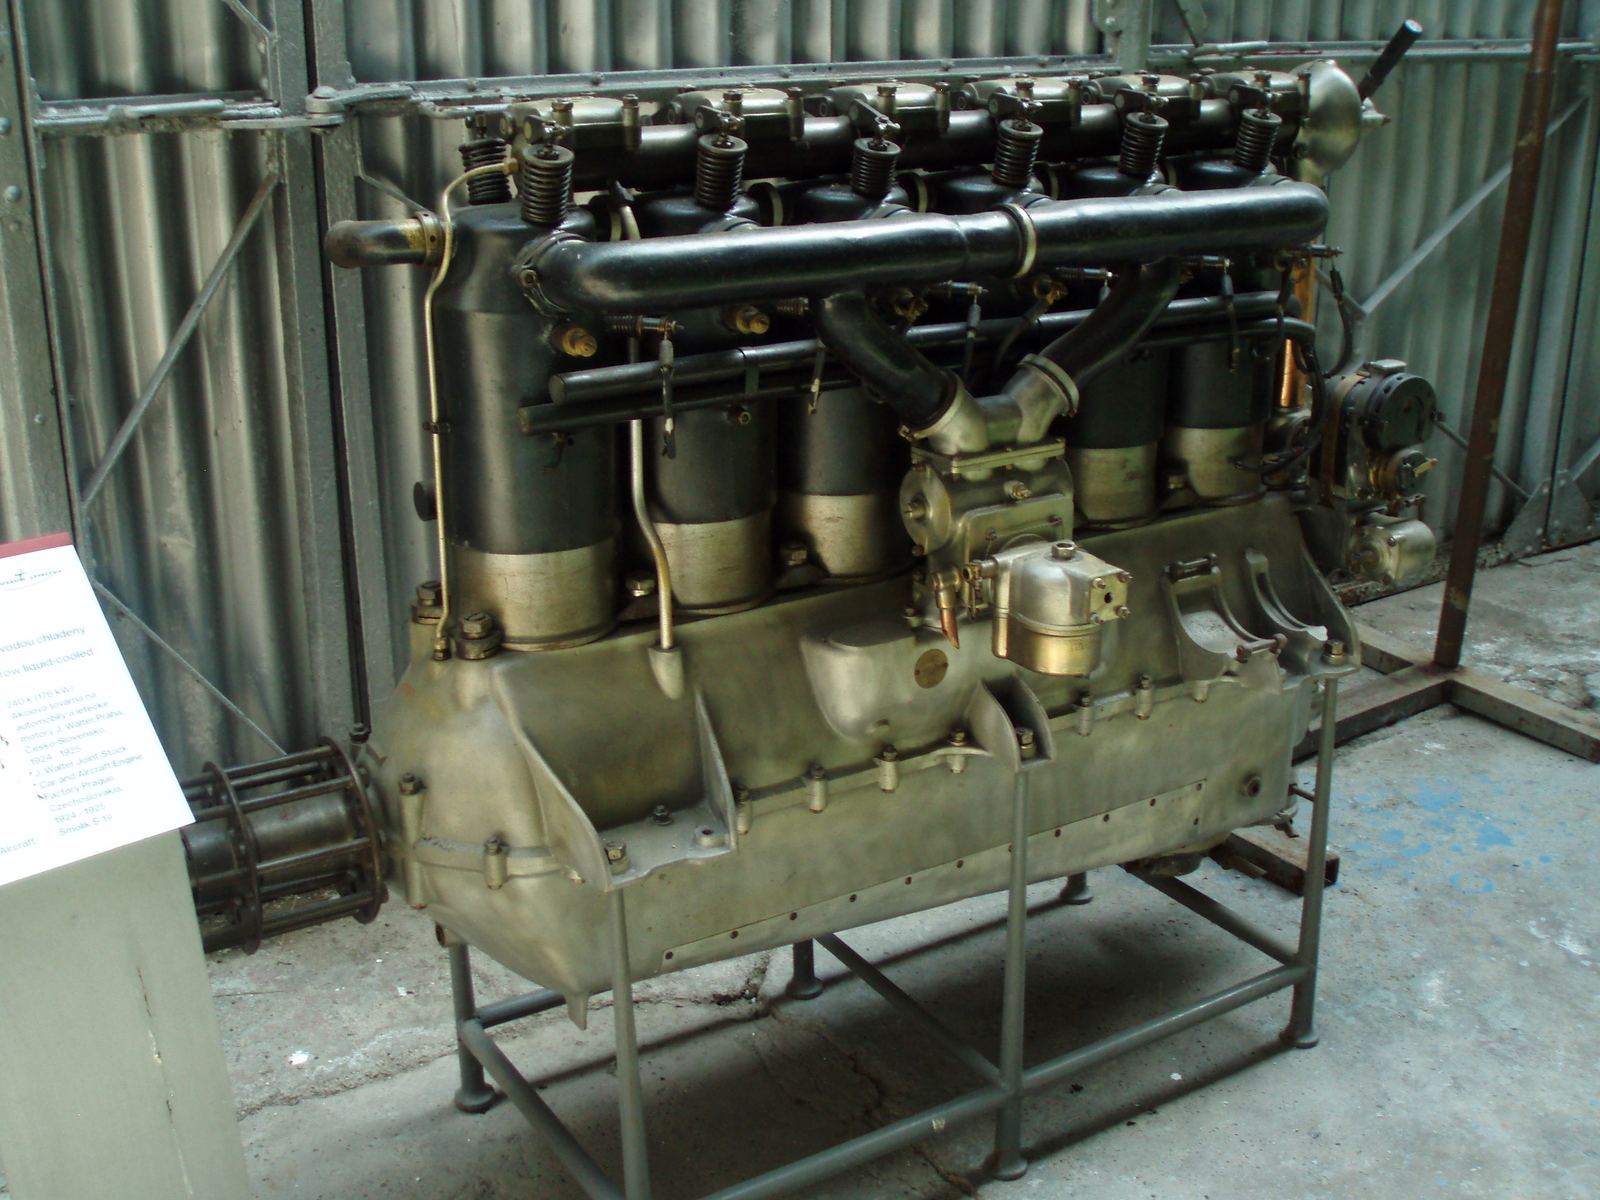
Walter IV aircraft engine, Museum of Aviation, Košice by ZemplinTemplar, 2010. CC BY-SA 4.0, via Wikimedia Commons. If the shaft spins, does the cage around it spin too?
No — it is bolted to the engine casing.
In the paper’s evaluation, GPT 6 Astra, Gemini 3.8 Flash and Claude Opus 5.5 each answered “yes, it turns with the shaft” on all three attempts. Fig. 13 · change & consequence
-
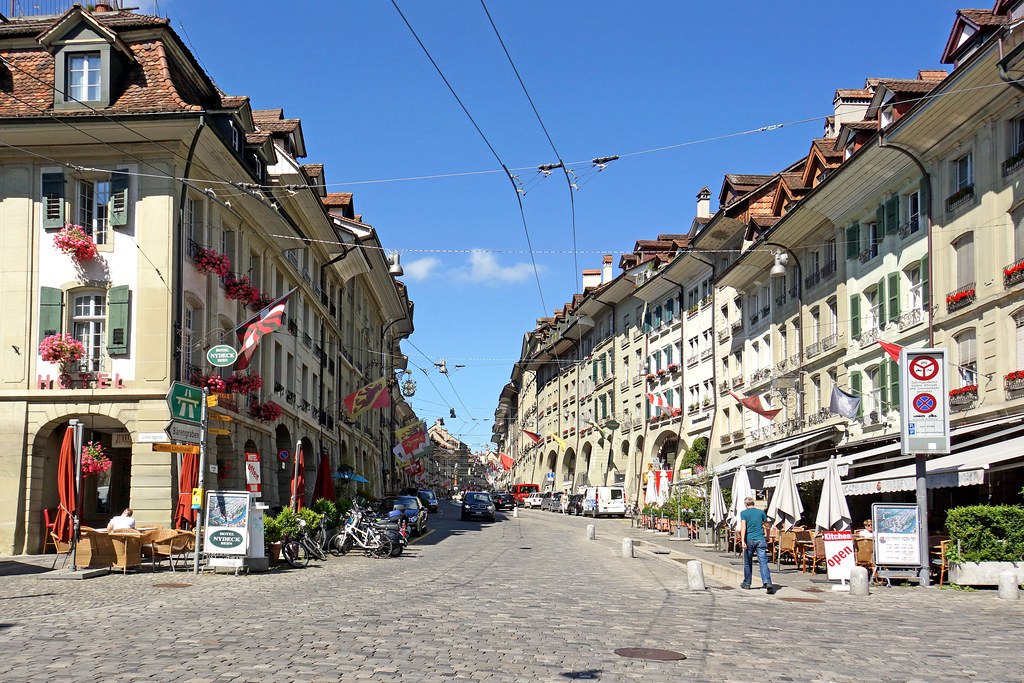
Which way is the wind blowing, from the striped flag?
Toward the camera.
In the paper’s evaluation, GPT 6 Astra, Gemini 3.8 Flash and Claude Opus 5.5 each answered “from right to left across the frame” on all three attempts. Fig. 9 · hidden & invisible
In the paper’s evaluation, GPT 6 Astra, Gemini 3.8 Flash and Claude Opus 5.5 each got every one of these wrong, on all three attempts. Most people find them easy.
Questions and answers are quoted from the HSS paper, Appendix E. The model answers are the paper’s LLM judge condensing what each model produced at the reasoning effort the paper used — GPT 6 Astra at max, Claude Opus 5.5 at xhigh, Gemini 3.8 Flash at high — with sampling temperature left at each provider’s default. These are results for particular model versions at the time that evaluation was run. Vendors update these models continuously, and a later version may well answer differently.
These questions are among the 522 in Humanity's Sixth Sense (HSS), a new benchmark we built in partnership with Scale AI. HSS measures how a model interprets and reasons through information a visual scene implies but doesn’t explicitly show. When a person looks at something, they can draw countless conclusions without significant thought. As we grow into adults we develop a sort of sixth sense, allowing us to conceptualize real-world scenes, including the spatial layout, context, and structural relationships beyond isolated objects.
This cognitive development grows gradually from infancy through childhood, driven by specialized brain regions and a framework known as “scene grammar.” By their early teens, most people can accurately sketch out a scene, even with limited visual cues and anticipate what will happen next. This is done largely by filling in the blanks and predicting actions based on past experiences. In theory, it seems like frontier models should excel in compiling complex information from a myriad of perspectives, leading to accurate predictions. Most models currently lack fundamental visual skills which would allow them to operate natively with visually-dependent tasks.
The whole picture
Model research has largely focused on text-based problems utilizing code, math, books, and exam questions. Most “visual” benchmarks test the same text-oriented flows. HSS is unique in that it tests simple visual reasoning, across four areas:
- Temporal & causal dynamics What happened before the scene, and what happens next.
- Physical & spatial logic What fits, what’s in reach, and what someone else can see from where they are standing.
- Social understanding Intent, attention, belonging.
- Abstract & contextual inference The patterns and rules a scene implies.
The benchmark is 522 tasks in all: 288 images and 234 short video clips, 17.6 hours of video between them.
What HSS measures
Frontier models write production code and pass professional exams. Given they also edit images and can identify objects in videos, it can seem like these models understand visual tasks better than they can. Most visual benchmarks reinforce that impression.
Humans are capable of visual reasoning well beyond what most visual benchmarks measure. We can usually tell what happened a moment before a photo was taken, whether a box will fit through a door, or why a dog took off running. Every question in HSS is open-ended, and answers are graded against rubrics written by humans. An answer only counts if it meets every point on the rubric, so a model can't pass by guessing.
Leaderboard
| Model | Effort | pass@1 | Image | Video | Time | Space | Mind | Context |
|---|---|---|---|---|---|---|---|---|
| Human baseline | — | 93.1 | 94.1 | 91.9 | 97.0 | 94.9 | 89.1 | 89.2 |
| GPT 6 Astra | max | 53.6 ±4.1 | 55.6 | 51.1 | 58.2 | 53.6 | 46.1 | 55.6 |
| GPT 6.1 Sol | max | 46.6 ±3.8 | 45.5 | 47.9 | 55.2 | 45.8 | 36.4 | 47.4 |
| Claude Opus 5.5 | xhigh | 44.6 ±3.8 | 51.3 | 36.5 | 44.0 | 44.9 | 34.8 | 55.6 |
| Gemini 3.8 Flash | high | 41.6 ±3.7 | 47.2 | 34.8 | 43.3 | 37.5 | 40.0 | 48.4 |
| Claude Fable 5.1 | xhigh | 40.8 ±3.6 | 44.7 | 36.0 | 43.3 | 41.1 | 34.2 | 44.1 |
| Gemini 3.7 Flash | high | 39.8 ±3.7 | 45.4 | 33.0 | 40.5 | 40.9 | 35.8 | 41.5 |
| Muse Spark 1.3 | max | 37.4 ±3.5 | 44.8 | 28.2 | 39.6 | 38.1 | 25.8 | 45.8 |
| Claude Fable 5 | max | 34.5 ±3.7 | 37.2 | 31.3 | 38.1 | 37.1 | 30.0 | 30.4 |
| Qwen 3.8 Max | max | 33.0 ±3.6 | 38.3 | 26.2 | 38.1 | 35.2 | 21.0 | 34.7 |
| Gemini 3.5 Flash | high | 32.6 ±3.4 | 35.1 | 29.6 | 35.6 | 31.6 | 31.8 | 31.4 |
| Gemini 3.6 Flash | high | 31.9 ±3.4 | 32.5 | 31.2 | 37.1 | 29.7 | 32.4 | 28.4 |
| GPT 6 Sol | max | 31.2 ±3.4 | 31.8 | 30.5 | 38.1 | 28.6 | 22.4 | 36.3 |
| Qwen 3.8 Flash | max | 30.9 ±3.3 | 37.2 | 22.9 | 37.9 | 29.2 | 18.6 | 37.1 |
| Claude Opus 5 | max | 30.5 ±3.5 | 32.5 | 27.9 | 31.3 | 35.0 | 22.4 | 30.1 |
| GPT 5.6 Sol | max | 30.0 ±3.3 | 28.5 | 31.9 | 38.6 | 26.3 | 27.3 | 28.1 |
| GLM 5.3 Flash | max | 26.8 ±3.0 | 30.2 | 22.6 | 31.3 | 26.3 | 18.2 | 31.0 |
| Kimi K3 | max | 25.5 ±3.1 | 29.1 | 21.2 | 33.1 | 27.4 | 15.5 | 23.2 |
| MiMo v2.6 Flash | high | 25.4 ±2.9 | 29.2 | 20.6 | 30.1 | 29.6 | 12.1 | 26.7 |
| MiMo v2.6 Pro | high | 25.2 ±2.9 | 30.4 | 18.6 | 28.3 | 29.5 | 14.5 | 25.7 |
| Claude Sonnet 5 | max | 24.8 ±3.2 | 29.5 | 18.9 | 29.1 | 27.5 | 14.2 | 25.8 |
| Muse Spark 1.2 | xhigh | 24.5 ±3.1 | 27.5 | 20.8 | 23.6 | 24.2 | 21.2 | 29.7 |
| Claude Opus 4.8 | max | 23.5 ±3.2 | 27.2 | 18.9 | 27.1 | 26.5 | 14.2 | 23.5 |
| GPT 5.6 Terra | max | 22.7 ±3.2 | 24.1 | 20.9 | 28.4 | 21.0 | 19.1 | 21.9 |
| GPT 5.6 Luna | max | 21.6 ±3.2 | 23.5 | 19.4 | 26.9 | 24.6 | 13.3 | 18.6 |
| GPT 6 Luna | max | 21.0 ±3.0 | 23.3 | 18.2 | 26.9 | 24.1 | 9.4 | 20.6 |
| GPT 6 Astra, media removed | max | 6.6 ±1.5 | 2.4 | 11.7 | 9.5 | 5.5 | 4.8 | 6.5 |
Twenty-five models from eight companies. Most score below 40%, and the median model scores 30.9%. The last row is the paper’s blind control — the strongest model, run again with the image or video taken away. It scores 6.6%, which is the floor you get from guessing at the question text alone.
Where models fail
HSS tasks are reasonably easy for the average person, with a baseline score of 93.1%.
Across the 8,573 individual failures the team labeled, 94% trace to seeing or inferring rather than to reasoning. The model misread something in the image in 53% of cases, and in a further 41% it failed to infer something the image implied but did not show. Only 5% came down to faulty logic.
The two most common single mistakes were (1) missing a detail that decides the answer (21% of failures) and (2) misidentifying an object, person, or role (20%). Failures were consistent across the 24 models that analysis covers. Struggling significantly with nuance, perspective, object variations, lighting effects, and causality. On tasks that five or more models failed, a median of 80% failed for the same reason.
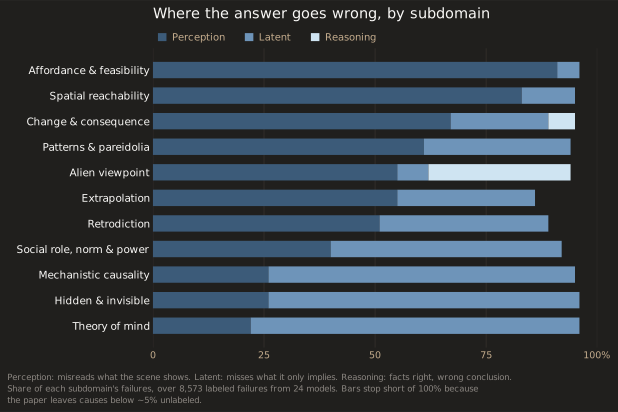
The weakest domain is social understanding — reading beliefs, intentions, and who defers to whom. It is the lowest-scoring domain for 21 of the 25 models, averaging 24.4% against 34.1% across the other three. Video is harder than still images for 23 of the 25 models, by 7.3 points on average.
Increasing reasoning effort helps overall, but on some skills it makes things worse. The paper reports a 14-point drop for GPT 6 Astra on retrodiction — working out what happened just before the moment shown — when reasoning effort is scaled from high to xhigh; the score then partly recovers at max. Best scores often came at a middle setting. Increasing reasoning effort on several models frequently led to the model overthinking or focusing on incorrect evidence.
Agent tools such as Claude Code and Codex modestly improved scores by letting a model crop, zoom, and take a second look. On the 388-task subset used for the agentic evaluation, the best setup reached 59.3%. A second look cut failures from 944 to 759 by catching missed cues and misread objects. What a closer look does not fix is depth: errors from reading a 2D overlap as 3D alignment were essentially unchanged, 102 to 101. Agents sometimes talked themselves out of answers they had gotten right the first time.
Humans noted that they mainly answered the questions intuitively. Typically spending more time explaining their reasoning than coming up with the correct answer. Many human failure cases could be traced to sloppiness, misunderstanding the question, and arithmetic errors. Author’s note: definitely never happens to me.
Is the horse walking towards you, or away?
Elorian is building the foundation of visual thinking. HSS is a preliminary step in identifying and understanding how to solve the complex gaps in frontier models. HSS highlights how today's models ability to see and interpret visuals is highly limited and not a quirk of one lab's model.
Read the paper The full leaderboard The dataset
Figures, questions and reference answers in this post are quoted from Humanity’s Sixth Sense: Benchmarking Intuitive Visual Reasoning in Multimodal Models, by Guo, Gu, Jang et al. — a joint paper from Scale AI and Elorian. Model results are as reported there, for the model versions and reasoning-effort settings used in that evaluation. Scores on this benchmark will move as vendors ship new versions; the leaderboard above is the current picture.